By Nikhil Kumar. Last updated October 2026.
The Reddit API did not get more expensive in 2026. It got harder to get at all.
The best Reddit data API in 2026 depends on a question the other lists skip: can you even get approved? Reddit now gates every developer behind a manual review, and the free .json workaround is dead. So the real choice is between fighting for official access or using a managed data API that reads Reddit’s public pages for you. This guide ranks six options by the thing that actually decides it: access, then coverage, then price.
“reddit api” draws about 5,400 US searches a month, according to DataforSEO keyword data pulled in September 2026. Most of the people typing it are about to discover that the API they remember is not the one that exists now.
What changed for Reddit data in 2026?
Two things, and both tightened access rather than price. In November 2025, Reddit’s Responsible Builder Policy extended pre-approval to every developer, including hobby projects. Then on May 28, 2026, Reddit deprecated the unauthenticated .json endpoint, and appending .json to a URL started returning 403. The free, no-questions-asked ways in are gone.
This is why last year’s Reddit API guide is wrong now.
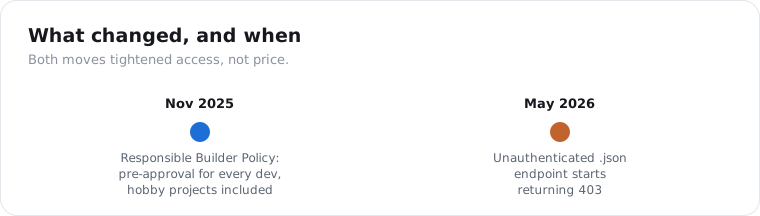
The Responsible Builder Policy is the bigger deal. It means you now request approval before Reddit issues your first OAuth token, the review runs about two to four weeks, and Reddit can deny you with no stated reason and no appeal. Developers on r/redditdev report careful, policy-aligned submissions getting rejected more than once.
The .json death closed the back door. That endpoint was the backbone of years of low-volume, informal Reddit access, and tools built on it silently broke. Reddit uses TLS fingerprinting and IP-reputation checks now, so changing a User-Agent header does nothing.
The nasty part is how it fails. Instead of a clean error, teams reported getting a 200 back with redirect HTML or empty JSON, so the pipeline looked like it ran, the job logged success, and the database came back empty. A quiet failure is worse than a loud one, because you find it a week later when someone asks where the data went.
Both moves trace to the same cause. Reddit’s data became a licensed AI-training asset, with reported deals worth around $130 million signed with Google and OpenAI, and the company closed the routes that let anyone take it for free.
What are the best Reddit data APIs?
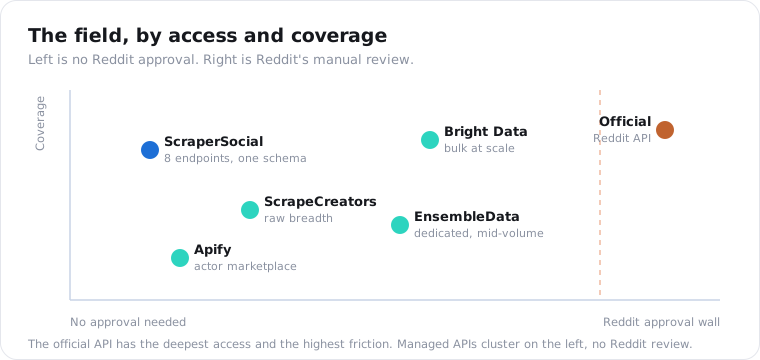
The six that most teams actually shortlist, ranked by how much access friction they remove. The official API is the cheapest if you clear approval. Everything below it trades some control for skipping the approval wall entirely. I have put the reason to pick each one in plain terms, not marketing.
- ScraperSocial. Eight Reddit endpoints inside a normalized API that spans 30+ platforms, per-item credit pricing, and no Reddit approval step, from $5/mo. Best when you want Reddit data in the same schema as your other social sources.
- Official Reddit Data API (with PRAW). Free at 100 queries a minute for non-commercial use, but behind the approval wall, and $0.24 per 1,000 calls plus a reported $12,000-a-year minimum for commercial use. Best for small, approved, non-commercial projects.
- ScrapeCreators. Pay-as-you-go with credits that never expire, Reddit alongside 20-plus other platforms, $47 for 25,000 credits. Best for raw breadth across many platforms.
- Apify. A marketplace of Reddit scraper actors, some with no login or key, billed on compute units from about $4 per 1,000 results. Best for custom or one-off pulls you want to tinker with.
- Bright Data. Enterprise proxy infrastructure and maintained datasets around $1.50 per 1,000 records, 5,000 free a month. Best for bulk historical Reddit data at real scale.
- EnsembleData. A dedicated social-data API with a Reddit endpoint set, free at 50 units a day, paid from $100/mo. Best for mid-volume teams that want a single support contact.
The category runs wider than six. SocialCrawl, FetchLayer, SociaVault, Oxylabs, and RedditAPI all sell Reddit data too, each with a slightly different pitch. The six above are the ones I see teams put on a real shortlist for Reddit specifically.
Which Reddit API does not require Reddit’s approval?
Any managed data API, because it never issues you a Reddit token. A third-party API reads Reddit’s public pages on its own infrastructure and hands you structured JSON, so the only key you need is theirs. ScraperSocial, ScrapeCreators, Apify, and Bright Data all skip Reddit’s dev-app review completely. You give up per-call tuning; you get to start today instead of in a month.
In 2026, that split decides more than any feature on a spec sheet.
Go through Reddit directly and you enter the approval queue: an application, a two-to-four-week wait, and a real chance of a denial you cannot appeal. That is fine for a moderation tool with time to spare. It is a project-killer for anything on a deadline.
Go through a data API and approval is not in the picture. You sign up, get a key, and make a call. The trade is that you cannot post or vote through most of them, and you are trusting their collection to stay reliable.
For a commercial product, that is usually the right trade. The engineering time you would spend building OAuth flows, managing rate limits, and appealing rejections costs more than the per-item fee.
How much do Reddit data APIs cost in 2026?
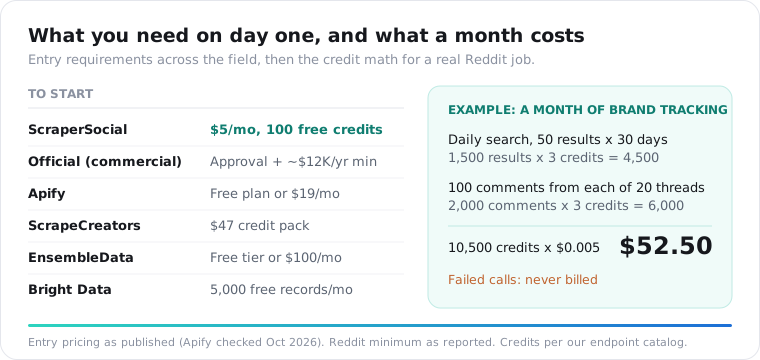
For a commercial Reddit project, the lowest paid monthly plan here is ScraperSocial’s $5: no contract, no Reddit review, and 25 free credits to test one subreddit call first. Compare that with the official commercial tier, which reportedly starts at $12,000 a year before the $0.24 per 1,000 calls. Managed APIs bill for the posts and comments you get back, not for the calls it took to find them.
| Route | Billing | Day-one cost | What you maintain |
|---|---|---|---|
| Official Reddit API | Free under 100 q/min; commercial $0.24 / 1,000 calls | Approval (2-4 weeks); reported $12K/yr commercial minimum | OAuth app, rate limits, pagination |
| ScraperSocial | Credits per item: 3 per comment or search result (at least 25 a call), 19 per post | $5/mo for 1,000 credits; 25 free | Nothing beyond the key; failed calls free |
| ScrapeCreators | Pay-as-you-go credits | $47 for 25,000 credits | One key |
| Apify | Per-result actors, about $4 / 1,000 results, plus run start events on pay-per-event actors | Free plan with $5 usage/mo; Starter $19/mo | Picking and configuring an actor per job |
| Bright Data | ~$1.50 per 1,000 records | Free tier of 5,000 records a month | Picking a dataset or scraper |
| EnsembleData | Daily units | 50 units/day free; $100/mo Wood tier | One key |
The number that trips people up is the official rate. $0.24 per 1,000 calls, set by Reddit in 2023, sounds trivial until you count calls, because Reddit meters calls, not records, and one call returns a single page. Our Reddit API pricing breakdown does that math in full.
Per-item pricing sidesteps the trap. A Reddit comment is 3 credits, 1.5 cents on the monthly plan, so your bill follows the comments you keep rather than how many pages a thread happened to span.
Here is a realistic month of brand tracking. A daily keyword search returning 50 results is 1,500 results, or 4,500 credits, and pulling 100 comments from each of 20 busy threads adds 6,000 credits. That is 10,500 credits, $52.50 on the monthly rate or $47.25 at the annual rate, with any failed call left off the bill.
Teams planning millions of Reddit records each month should also request bulk per-record quotes.
Reddit’s official API vs a data API: which should you use?
Use the official API if you are small, non-commercial, and can wait for approval. Use a managed data API if you are commercial, on a deadline, or done maintaining scraping infrastructure. The line is not really price. It is whether you can afford the approval wait and the ongoing engineering the official route demands.
Think of it as control versus speed.
The official API gives you the most control: real-time data, write access to post and vote, and Reddit’s blessing. In exchange you own the OAuth app, the rate-limit backoff, the pagination, and the risk that your application gets denied.
A data API gives you speed. One call with a subreddit or a keyword returns clean JSON, and the collection headaches are someone else’s problem. In exchange you cannot write, and you are betting on their uptime.
I keep coming back to one test for this. If losing API access for two weeks would kill your project, do not build on a route where Reddit can deny or revoke you without explanation. That single question sorts most teams correctly.
What should you check before you pick a Reddit data API?
Four things the pricing tables hide: how deep the comments go, how far back the history reaches, how fresh the data is, and what happens when a post gets deleted. These decide whether the data is actually usable, and almost no comparison mentions them. Price is the easy part. Coverage and freshness are where projects quietly break.
Start with comment depth. A lot of Reddit’s value lives in the replies, not the top-level comments, so a tool that flattens threads or stops at the first level throws away the part you came for. Ask whether nesting is preserved before you commit.
Then historical range. Live APIs only see what is up right now. If you need five years of a subreddit, you are looking at community archives like PullPush or Arctic Shift, and their coverage after 2023 has real gaps. Current-data tools and historical archives are different products, and mixing them up wastes a week.
Freshness is the one that burns you silently. Some archive sources report a score of 0 or 1 on anything younger than roughly a day and a half, because they read the post before Reddit finished counting votes. If you are tracking a launch in real time, a lagging source does not error out. It just lies to you with confident-looking numbers.
Last, deleted-content handling. The 48-hour purge rule is more than a legal box to tick. A well-built API stops serving content Reddit has removed, which keeps your database compliant without you writing the cleanup job yourself. A cheap scraper that keeps returning deleted posts hands you a liability you did not ask for.
None of this shows up in a per-1,000 price. All of it shows up in whether the project ships.
Can you use Reddit data to train an AI model?
Not through the official API without a licensing deal, and not casually anywhere else. Reddit’s Data API Terms prohibit training machine-learning or AI models on Reddit content without a separate written agreement. That clause is the whole reason Reddit closed the free routes and signed paid deals with Google and OpenAI. For any AI-training use, this is a legal question, not a technical one.
That clause catches a lot of teams off guard.
The instinct in 2026 is to grab a pile of Reddit threads and fine-tune something on them. Reddit’s terms say no, and the AI-training restriction is exactly what the Responsible Builder Policy was written to enforce.
There is a second obligation people miss. If content is deleted from Reddit, you are required to delete it too, down to the author-identifying fields, and Reddit strongly recommends purging stored user data within 48 hours. That is real engineering work, and it applies whether you use the official API or a third party.
None of this is legal advice. If your use is commercial or involves model training, run it past counsel before you collect a single row.
How do you pull Reddit data without the approval wall?
You send one request to a managed endpoint and get structured Reddit data back, with no OAuth app and no Reddit review. The API handles collection, rate limits, and the approval problem, and bills you per item returned. That removes the two things the official route forces you to own: the throttling code and the two-to-four-week wait for a token.
With ScraperSocial, the eight Reddit endpoints map to what people actually pull: a subreddit’s posts, a keyword search, a post and its comments, and a user’s history.
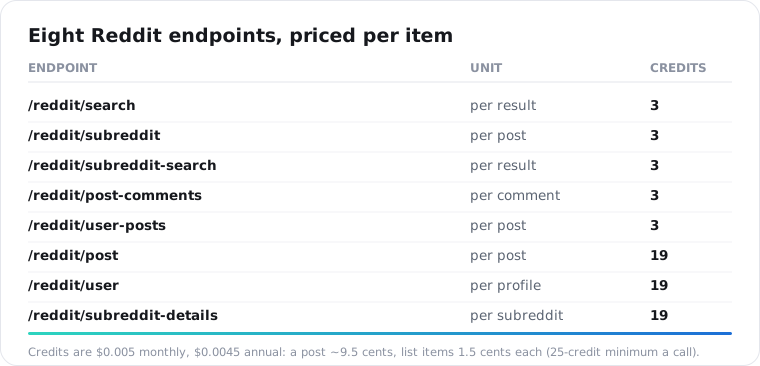
Credits are $0.005 each monthly and $0.0045 annual, so a subreddit post, a search result, or a comment is 1.5 cents, with a 25-credit minimum per call, and a full post lookup is 9.5 cents. You send a keyword to /v1/reddit/search, a post URL to /v1/reddit/post-comments, or a subreddit to /v1/reddit/subreddit, and every response comes back in the same envelope.
import requests
r = requests.get(    "https://api.scrapersocial.com/v1/reddit/search",    params={"query": "your brand", "limit": 50},    headers={"Authorization": "Bearer sk_live_..."},)print(r.json()["data"])
The free signup credits cover exactly one list call, enough to see exactly what the envelope looks like on a subreddit you care about before paying for anything.
Which Reddit data API should you pick?
Start with the approval question, not the price. If your project is small, non-commercial, and can survive a rejection and a wait, Reddit’s free tier with PRAW is still the cheapest data that exists. If you are commercial, on a clock, or tired of maintaining scraping code, pick a per-item data API and skip the wall: ScraperSocial for one schema across platforms, ScrapeCreators for raw breadth, Bright Data for bulk scale. Answer “can I get approved, and can I wait” first, and the row picks itself.
Frequently asked questions
What is the best Reddit data API in 2026?
There is no single best one, because it depends on whether Reddit will approve you. For a small non-commercial project, Reddit’s own free tier with PRAW is still the cheapest path if you get through approval. For commercial use or anything that must ship this week, a managed data API like ScraperSocial, ScrapeCreators, or Bright Data skips the approval wall and bills per item. Pick by approval risk first, then price.
Is the official Reddit API still free?
Yes, within limits, but access is no longer automatic. The Data API stays free at 100 queries per minute per OAuth client for non-commercial use, but since the Responsible Builder Policy of November 2025, every developer must apply and be approved before their first token works, including hobby projects. Commercial use is billed at $0.24 per 1,000 calls behind a separate approval and a reported $12,000-a-year minimum.
Which Reddit data API does not require Reddit’s approval?
Managed third-party data APIs do not touch Reddit’s approval process, because they read Reddit’s public pages for you instead of issuing you an OAuth token. ScraperSocial, ScrapeCreators, Apify, and Bright Data all return Reddit data with just their own API key and no Reddit dev-app review. You trade the ability to tune each call for skipping the 2-to-4-week approval wait entirely.
Can I use Reddit data to train an AI model?
Not through the official API without a licensing deal. Reddit’s Data API Terms prohibit training machine-learning or AI models on Reddit content without a separate written agreement, which is why Reddit signed reported deals with Google and OpenAI worth about $130 million. For public-data collection through a third-party API, the same restriction on Reddit’s terms applies, so treat AI-training use as a legal question for counsel, not a settled yes.
How much does Reddit data cost at scale?
For a mid-sized commercial job, far less than the official route. Reddit’s commercial tier reportedly carries a $12,000-a-year minimum on top of $0.24 per 1,000 calls, while a ScraperSocial plan costs $5 a month, needs no approval or contract, and comes with 25 free credits. A Reddit comment is 3 credits, so 10,000 comments cost $150 on the monthly rate, and failed calls are never billed.
Do I have to delete Reddit data if a user deletes their post?
Yes, if you are using the official API under Reddit’s terms. Reddit requires you to delete content that has been removed from Reddit, including titles, bodies, embedded URLs, and author-identifying fields, and strongly recommends purging stored user data within 48 hours. This deletion obligation is one of the most overlooked costs of building on Reddit data, and it applies regardless of which access method you use.
Answer the approval question first
Before you compare a single price, decide whether you can get approved and whether you can wait. If yes, Reddit’s free tier is the cheapest Reddit data there is, and PRAW makes it easy. If no, a per-item data API gets you moving today. Point a key at the Reddit search endpoint with a keyword you actually care about and read the response before you decide anything. The quickstart hands you that key in about a minute, the pricing page shows the per-item credit cost, and your first 25 credits are free, which is one list call, enough to check the envelope on a subreddit against your own use case before a card is ever involved.